
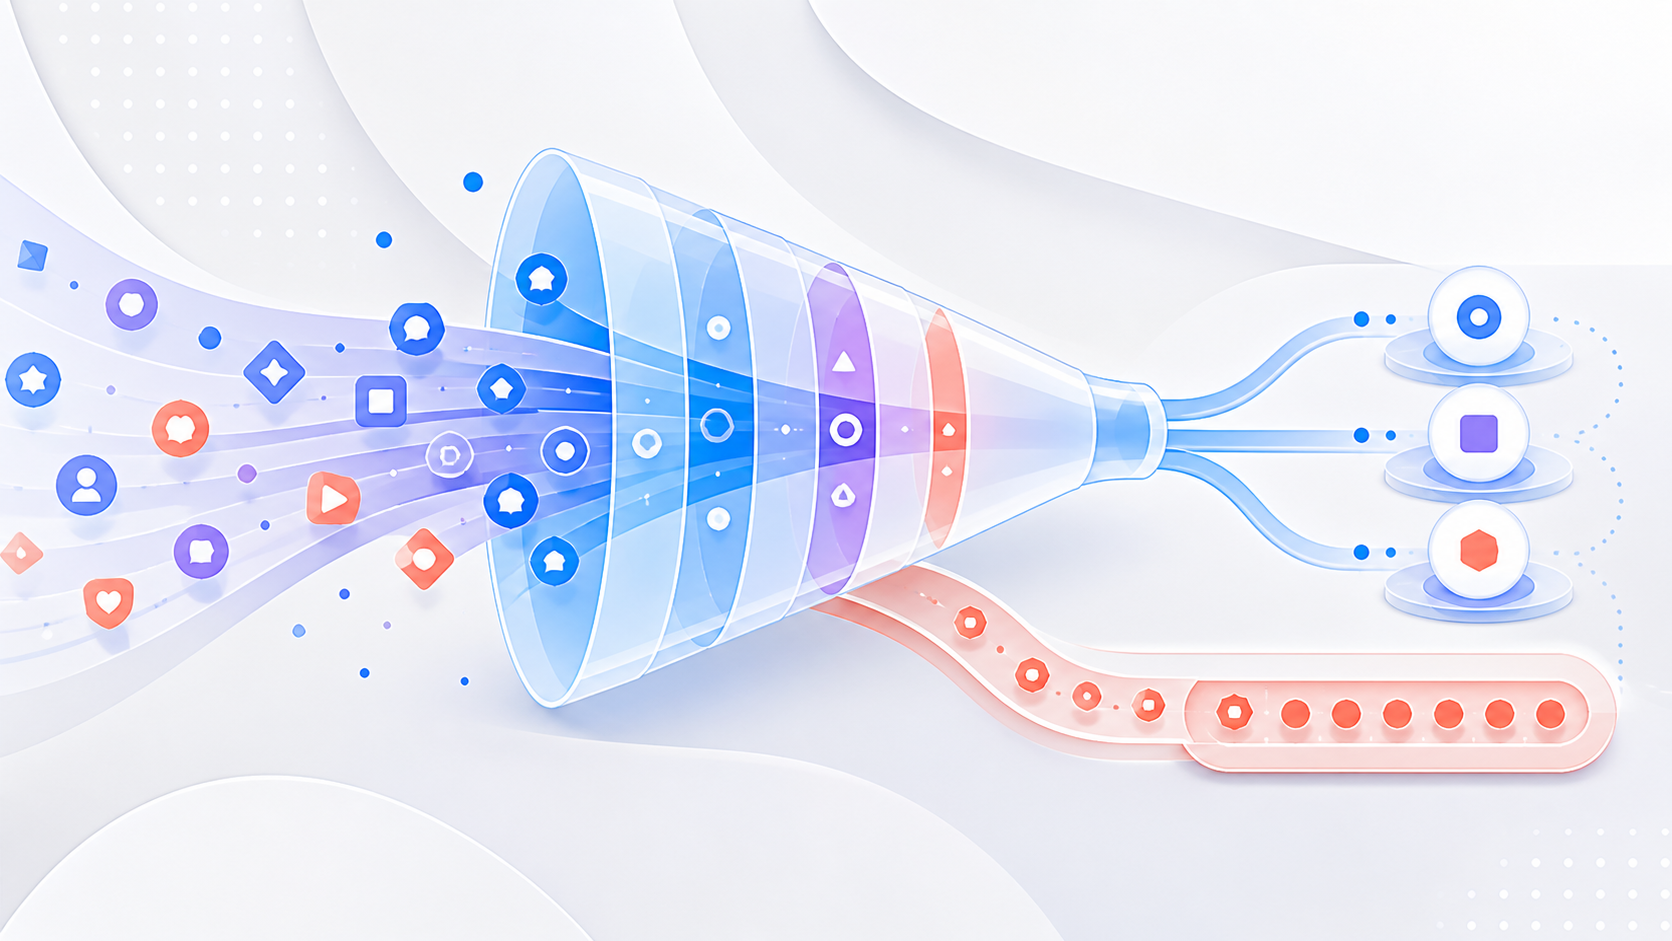
AI capacity planning starts with an uncomfortable question: when the assistant gets busy, who is available to catch the work it cannot finish? Small teams often size an AI rollout around model speed or token cost, then discover the real constraint is the human queue behind it. A helpful assistant does not remove demand. It changes where demand lands, how quickly it arrives, and how much context a person needs to recover.
Table of Contents
The human queue is part of the product
Consider a website assistant that can answer routine product questions at any hour. That is valuable coverage. But the important operational question is not only how many conversations it can open. It is how many conversations it escalates, what arrives with each escalation, and whether a real person can respond while the intent is still warm.
This is why an AI latency budget matters beyond model performance. A fast acknowledgement is useful only when the slower path has an honest next step. If a visitor is told that a specialist will follow up, that promise creates work for a finite human team. AI capacity planning makes that dependency visible before the queue becomes a customer-experience problem.
The same principle applies inside a business. An assistant that turns every ambiguous request into a polished draft may increase review volume faster than it reduces first-pass work. A model can create more plausible options than a manager can responsibly inspect. The bottleneck moves from production to judgment.
AI capacity planning starts with demand
Good AI capacity planning starts with the work arriving at the system, not a benchmark chart. List the requests that matter: contact forms, support questions, proposal drafts, account changes, or internal research. Then ask four practical questions for each lane.
- What does a normal day look like, and what does a peak look like?
- What share can the assistant finish safely without a person?
- What share needs a review, decision, or human relationship?
- How long can that request wait before the value of a response drops?
You do not need a perfect forecast. You need a shared picture of demand and a willingness to name the peak. Operations teams have long used queueing ideas such as Little’s Law to connect work in progress, arrival rate, and time in a system. For an AI-enabled lane, the useful translation is simple: if more cases arrive than the combined assistant-and-human service path can clear, wait time grows. A better model does not repeal that arithmetic.
Start with one week of lightweight evidence. Count incoming requests, note when they bunch up, and tag the reason each one needed a person. The goal is not surveillance. It is to distinguish productive escalation from avoidable escalation. If pricing questions dominate, perhaps the source material is incomplete. If custom requests dominate, perhaps that is the honest boundary of the service. Both findings are useful.
Design a queue that can tell the truth
A queue should not be a dark drawer where an agent places its uncertainty. It should tell the next person what happened, why the work needs them, and what promise has already been made. That is the difference between escalation and abandonment.
Give every handoff a small service card: customer intent, relevant source or page, what the assistant already tried, the reason it stopped, and the response window. This builds on the idea that an AI handoff is a product surface, not a transcript dump. It also lets a team sort work by consequence rather than by the order a model happened to produce it.
Then give the queue three visible states: within capacity, approaching capacity, and overloaded. Each state needs a humane behavior. Within capacity, the assistant can make its normal promise. Approaching capacity, it can set a longer but specific expectation or route lower-consequence work to a deferred lane. Overloaded, it should stop pretending that instant service exists. It can capture intent, explain the next step plainly, and avoid generating commitments that nobody can meet.
This is consistent with the Google SRE guidance on handling overload: load shedding and graceful degradation are service choices, not admissions of failure. For a small business, graceful degradation may mean a short acknowledgement and a well-prepared human follow-up rather than a long, uncertain AI conversation.
Make capacity a weekly operating question
AI capacity planning is not a one-time sizing exercise. A new campaign, a product change, or a better assistant can change demand overnight. Spend fifteen minutes each week looking at volume, handoff rate, age of the oldest open case, and the top reason work reached a person. Those four signals are enough to start a useful conversation.
When the queue is healthy, decide what the assistant can take on next. When it is strained, improve the source, narrow the lane, add a response owner, or revise the promise. Do not solve every capacity signal by adding more autonomy. Sometimes the best improvement is a clearer boundary that protects the team and the customer.
The strongest AI systems make human attention more useful, not invisible. Build the model into the workflow, certainly. But build the human queue into the product too. That is where a fast demo becomes dependable coverage. The point is not to turn people into a queue-management system; it is to make the customer promise match the capacity actually behind it.
Leave a Reply