
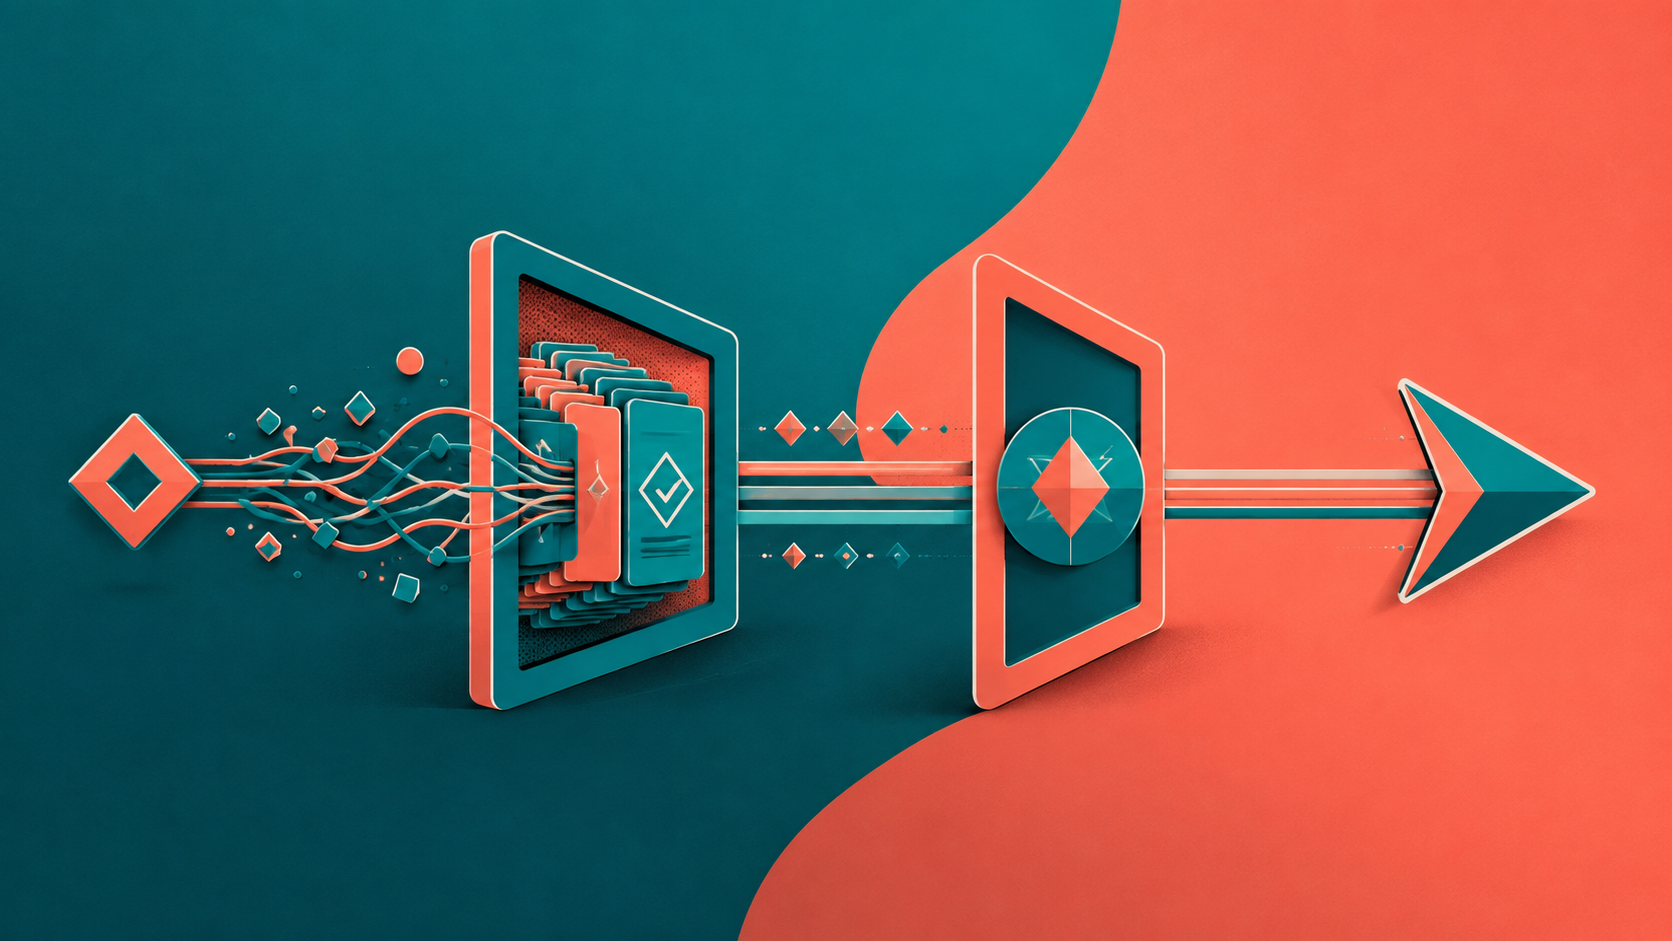
Decision latency is the time between a business question arriving and someone being able to make a responsible next move. It is a better test for business AI than how quickly a model can produce a paragraph. A fast answer that still needs hunting, checking and a second meeting has not made the organisation faster.
Table of Contents
Decision latency is not response time
Model response time matters when a visitor is waiting on a website or an operator is trying to finish a task. But it is only one small part of the clock. The more expensive delay often starts after the response: a manager has to ask which source was used, an account owner has to find the customer history, or a team has to decide whether the recommendation is safe to act on.
This is why a fluent assistant can look impressive while leaving the real work untouched. It may compress typing but not uncertainty. The practical question is not, “How quickly did the AI answer?” It is, “How quickly did the right person reach a defensible next move?”
The distinction is useful because it changes what a team builds. A website assistant should not just reply quickly; it should help a visitor find the approved evidence, state what it cannot confirm, and make the next route clear. That is the same logic behind after-hours website coverage: coverage is valuable when it preserves momentum without pretending that every question is settled.
Find the wait, not the task
Teams often begin with a task list: draft the reply, summarise the call, classify the lead. That is a sensible inventory, but it can miss the bottleneck. A reply may take two minutes to draft and two days to approve because the pricing exception is buried in three systems. Summarising the call may be easy; deciding who owns the follow-up may be the real delay.
Trace one recurring customer or operating request from arrival to action. Mark every moment it waits for context, a source, a decision-right, or a human judgement. The result is a small map of decision latency, not a grand process-reengineering exercise.
- Context wait: the needed account, policy or conversation history is hard to retrieve.
- Evidence wait: people cannot see the source behind a recommendation.
- Authority wait: nobody is sure who may approve an exception.
- Judgement wait: the case is genuinely consequential and needs a person.
An AI system should reduce the first three without disguising the fourth. The design of an AI review queue matters here: a real exception arrives with its trigger, evidence, owner and expiry, rather than as a vague message asking someone to “take a look.”
Design for a smaller decision latency
The best intervention is usually modest. Give the assistant a bounded job, the sources it may use, and a result shape that lets a person decide. That approach fits the NIST AI Risk Management Framework: trustworthy use is not a property that appears inside a model; it is managed through the surrounding system and its choices.
For each high-frequency request, define four things: the question being answered, the evidence that must travel with the answer, the person who can make the next decision, and the point where the system must stop. This turns decision latency into a design constraint. The assistant can prepare a clear handoff; it does not need to impersonate the final authority.
It also makes model choice more practical. A local or private model may be the right first step when sensitive context cannot leave the business. A stronger cloud model may be appropriate for a tightly bounded research task. The question is not which model wins a benchmark; it is whether the whole path to a responsible action becomes shorter, clearer and easier to audit.
Measure the next move
Do not start with a dashboard full of model metrics. Pick one workflow and record a simple before-and-after: when the request arrived, when the evidence was ready, when a person made the next move, and why it paused. This resembles the delivery-performance focus of DORA’s four key metrics, which look at the flow of useful change rather than isolated effort.
Then review the pauses. If the same question keeps waiting for a missing policy, improve the source. If the same exception keeps reaching a manager, make the decision rule explicit. If the assistant confidently advances cases that need care, tighten the stop condition. Lower decision latency should mean fewer blind steps, not fewer humans.
A useful first experiment can be deliberately small: take the ten most recent requests in one lane and ask what delayed each next move. Do not score the assistant on eloquence. Score the packet it prepares: was the relevant context present, was the source visible, was the decision owner clear, and did the case stop where human judgement was needed? The answers show whether the delay is a model problem, an information problem, or an ownership problem.
This keeps improvement honest. Sometimes the fastest way to reduce decision latency is not a new model or more autonomy. It is a current price list, a named fallback, or a clearer rule for what the assistant must never decide. Those changes may look less dramatic in a demo, but they are what make a real operating day move.
That is a better promise for AI in a small business: not an autonomous showpiece, but a system that helps the right person act sooner with their judgement intact. When an answer makes the next move obvious, accountable and reversible, the technology is finally doing business work. You’ve got this.
Leave a Reply