
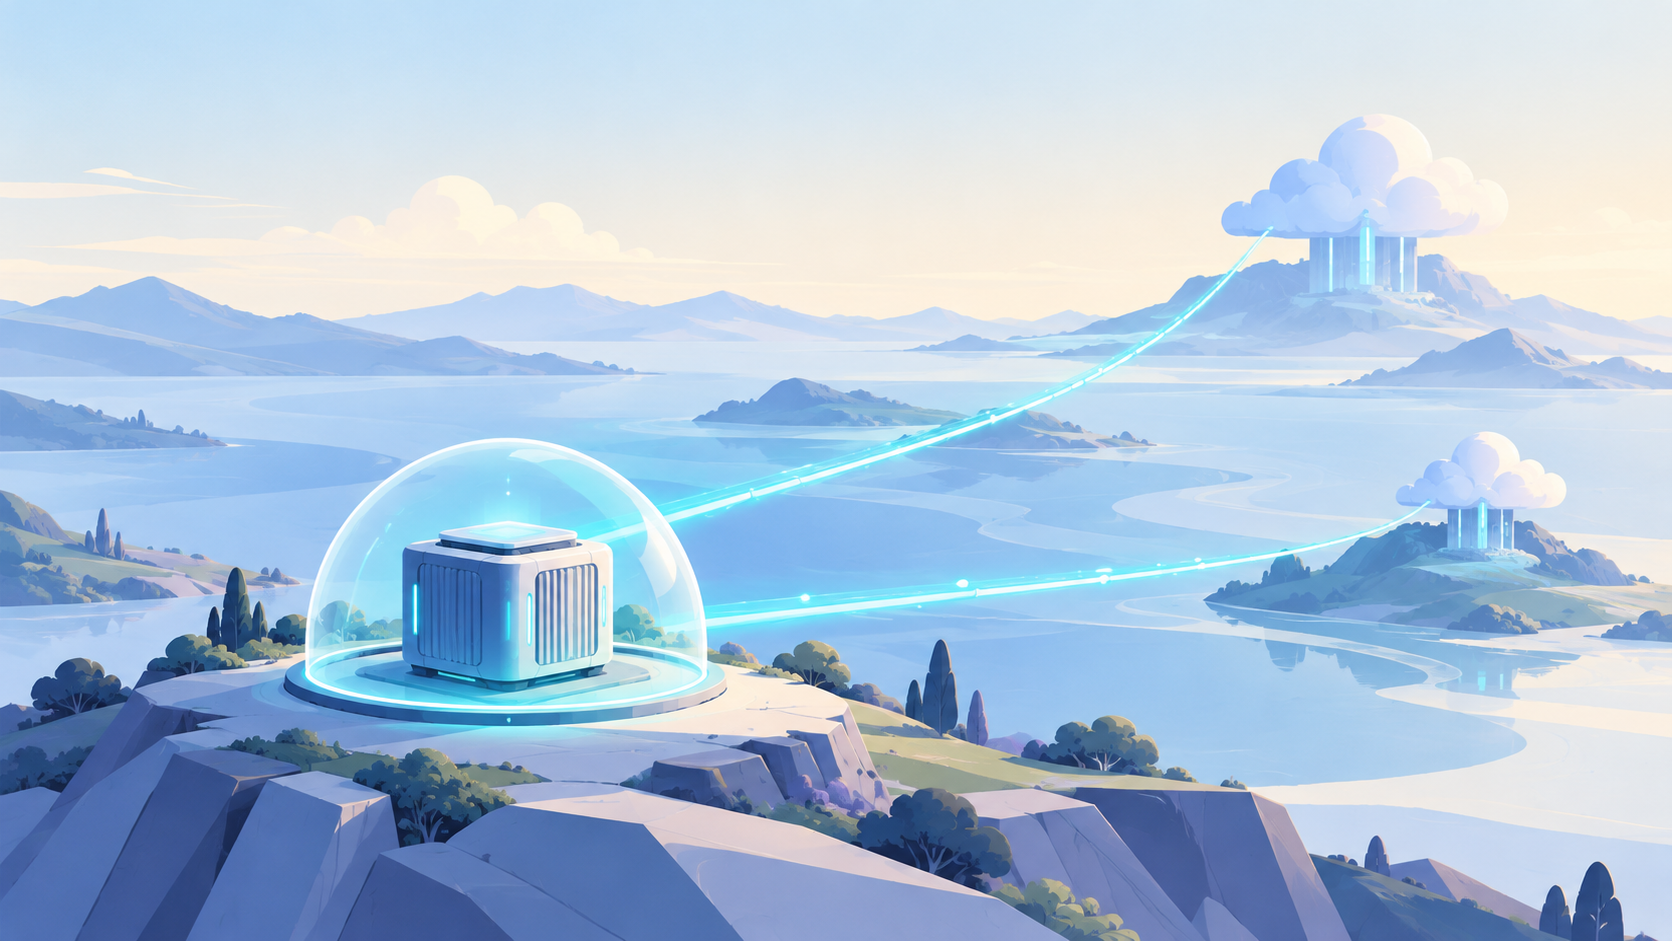
Liquid D1 is a new open-weight decision-model family aimed at a question many AI products still avoid: which decisions should happen close to the user, device or business system instead of being sent to a large remote model by default?
In this article
The big signal
Liquid AI has released Liquid D1 as two open-weight decision models: d1-3B for text and images, and an experimental d1-omni-600M for text with either image or audio inputs. They are designed to return a decision in a single forward pass rather than generate a long sequence of tokens. That makes them a different building block from a conversational assistant.
The company reports that its 3B model reaches 48.57 on Decision Index v0.2.1’s public split, ahead of the sub-10B models it compared, and reports low-latency results across NVIDIA hardware. Those are vendor-reported benchmarks, not a reason to skip a deployment test. The more durable signal is architectural: a modest model can handle a bounded decision without making every small judgement into a cloud conversation.
That can change the shape of an agent system. Instead of asking one large model to interpret every input, choose a small set of decisions that have stable labels, measurable mistakes and a safe fallback. A compact model may decide whether an image is complete, whether an incoming request matches a known route, or whether audio contains a supported intent. The larger model can then spend its context and latency budget where it adds real value: explaining, synthesising, negotiating ambiguity or preparing a human handoff.
That distinction matters. A support assistant may need a frontier model to explain a complex policy or guide a customer through an unfamiliar choice. But a product can often keep narrower work close to home: deciding whether an uploaded photo is usable, routing an enquiry, checking whether a document needs review, or selecting a safe next step from a known set. A decision model does not replace reasoning everywhere. It makes the system’s routing choices more deliberate.
Open-source watch
- Whistle: Cactus Compute’s 16.9 MB speech-to-text project is another reminder that small local components can be useful when the task is clear. It is a narrower release than Liquid D1, but it points in the same direction: reduce the footprint before assuming the cloud is mandatory.
- LightOnOCR-3: LightOn’s recently posted OCR and layout-extraction model shows how document understanding is becoming a more specialised layer. For business workflows, extracting structure reliably is often more useful than asking a general chatbot to guess at a PDF.
- Open weights, bounded jobs: The opportunity is not to swap every hosted model for a local one. It is to give repeatable, privacy-sensitive and latency-sensitive steps their own measured lane.
Why Liquid D1 matters for meLink
For meLink, Liquid D1 reinforces a practical view of orchestration: model choice is part of product design, not a leaderboard reflex. A website assistant can use a capable hosted model for open-ended customer language while a smaller local or tightly scoped model handles a bounded classification, visual check or handoff decision. The customer should see one clear experience; the system should keep the responsibilities separate.
This is especially relevant where data handling, response time and cost are all real constraints. A business should not promise local processing merely because it sounds safer, and it should not send everything away merely because a large model is convenient. Start with a reference task: one recurring job, an explicit acceptable outcome, known inputs, a clear escalation path and a way to measure errors.
The boundary has to remain visible. If a small model can classify an image or prepare a route, that does not grant it authority to make a consequential promise, update a customer record or take an irreversible action. Those need permissions, traceability and a revocation path. Local inference can improve control, but control comes from the surrounding system design.
The practical takeaway
Liquid D1 is not a call to move every agent to the edge. It is a useful prompt to stop treating every AI task as the same task. Separate open-ended conversation from bounded decisions. Keep simple, measurable work close to the system when that improves latency, privacy or operating cost. Escalate when ambiguity or consequence requires stronger reasoning and human judgement.
For builders and small teams, the first experiment is straightforward: pick one decision that is currently hidden inside a larger model call. Define the allowed inputs, measure the false-positive and false-negative cost, test a compact model against a rules-based baseline, and retain a human or stronger-model route for uncertain cases. The useful win is not a smaller model for its own sake. It is a clearer system that knows which decisions belong where. That separation gives teams an evidence trail to improve safely.

Leave a Reply