Nvidia Reflection AI talks are suddenly the open-weight story to watch. Reuters reported on 10 October that Nvidia is in early discussions to deepen its investment in Reflection AI or acquire it; neither company had confirmed a transaction when the report was published. The timing matters because Reflection introduced Beam, its first open-weight model, only days earlier.
Nvidia Reflection AI: the big signal
Nvidia Reflection AI talks are not a product launch and not a completed acquisition. They are, however, a useful reminder that the boundary between the companies supplying AI compute and the teams building the models is getting thinner. Reuters, citing Financial Times reporting, said the discussions could lead to more investment, an acquisition, or an acqui-hire-style arrangement — and could still fall apart.
That nuance is important. A headline about a possible deal is not evidence that a company’s roadmap, licence, API access or model weights have changed. Builders should not make architecture decisions on it. But the report lands at a revealing moment: Reflection’s official Beam announcement describes a 501-billion-parameter sparse mixture-of-experts model, with 23 billion parameters active per token, aimed at coding, reasoning and agentic work. The company says it plans to release weights and developer materials later this month.
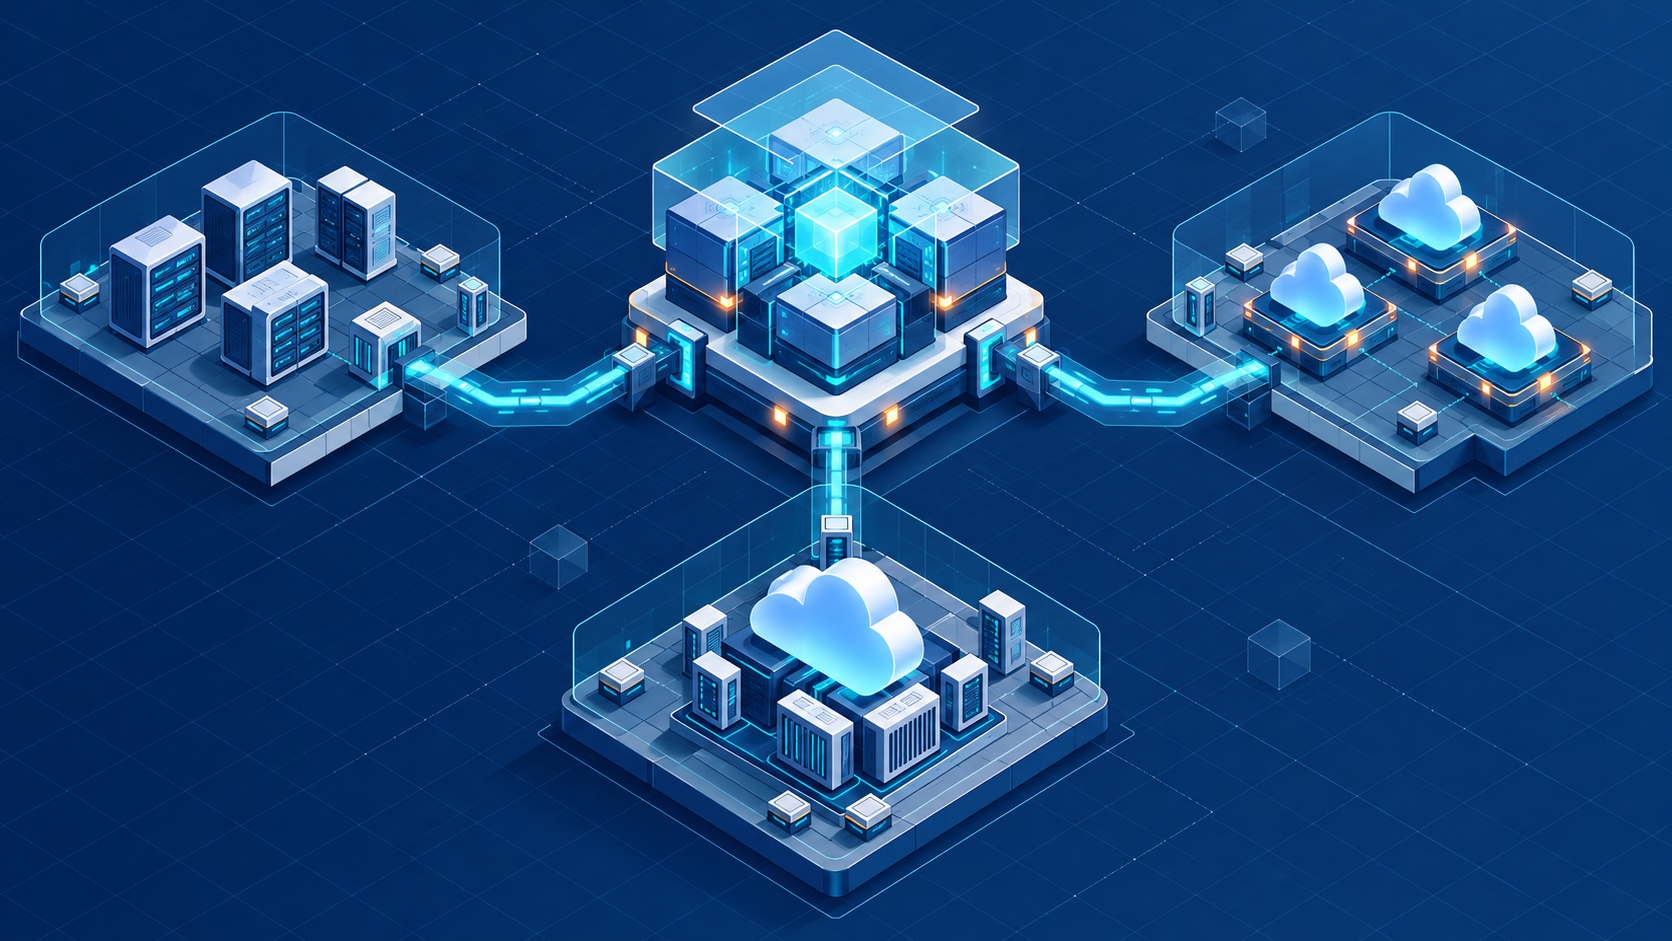
That makes this less about one corporate transaction than about where open-weight capability is being assembled. The next generation of practical agents needs more than an impressive benchmark: it needs models that can be evaluated, served, adapted and moved between environments without turning a supplier relationship into a hidden single point of failure.
What a deal could change
If the Nvidia Reflection AI discussions produce a deal of any kind, the central question for customers will be operational independence. “Open-weight” is valuable because it can give teams options: self-hosting, private-cloud deployment, fine-tuning and alternative serving stacks. Those options are only real when the release terms, artifacts and deployment path are clear.
- Watch the artifacts, not the adjectives. A model announcement is not a deployable model. Check for released weights, licence terms, a model card, evaluation detail and reproducible serving guidance.
- Separate compute preference from model portability. Nvidia hardware may be the right operational choice while the model layer still needs a clean exit path to another host, provider or runtime.
- Keep evaluation outside the vendor relationship. Use task-specific tests, cost ceilings, safety checks and rollback criteria. Our guide to AI contract testing is a useful pattern: test the behavior you rely on, not just a model’s branding or leaderboard position.
There is a second-order issue too. As chips, cloud capacity, inference software and model labs become more intertwined, it becomes harder for small teams to understand which parts of their stack are genuinely interchangeable. That is why model portability is not procurement paperwork. It is an engineering decision that should be made before an assistant is wired into customer conversations or business workflows.
Open-source watch
It was a quieter 24 hours for major releases, but a few signals are worth keeping in view alongside the Nvidia Reflection AI report:
- Beam remains the immediate open-weight release to track. It is not new news today, and meLink covered its launch earlier this week. The fresh delta is the reported strategic interest around the company before its planned developer release.
- LightOnOCR 3 is a reminder that useful open work is not limited to giant general-purpose models. Document extraction and structured visual understanding can be more commercially relevant than a broad benchmark win when an agent has to read a real business process.
- Decision-model work in llama.cpp points in the opposite direction: smaller, controllable local inference paths for narrow decisions. That matters when privacy, latency or offline operation is part of the requirement.
The common thread is not that every workload should run locally or that every serious deployment should use open weights. It is that a healthy agent stack needs choices at more than one layer: model, runtime, data boundary and approval path.
Why this matters for meLink
For meLink, the practical lesson is to design assistants around controlled handoffs rather than a permanent commitment to one model vendor. A website sales assistant needs dependable answers, consent-aware access to business information and a way to escalate uncertainty. An orchestration system needs the same discipline: select a model for a defined job, record the decision boundary, and preserve the option to switch when cost, capability or privacy requirements change.
The Nvidia Reflection AI story is useful precisely because it is unsettled. It shows why teams should build the guardrails before market structure forces their hand. Model choice is not a one-time shopping decision; it is a living operational dependency.
The practical takeaway
Treat the reported talks as a monitoring event, not a reason to rewrite a roadmap. If Beam’s weights and developer tools arrive as Reflection has indicated, evaluate the release on its own terms. If a transaction is later confirmed, revisit the questions that actually affect deployment: who controls access, what can be self-hosted, how portable are the artifacts, and how quickly can you test a substitute?
The winning position for a small business or builder is not predicting every deal. It is having an agent architecture that can absorb change without putting customer trust, data boundaries or delivery speed at risk.

Leave a Reply