
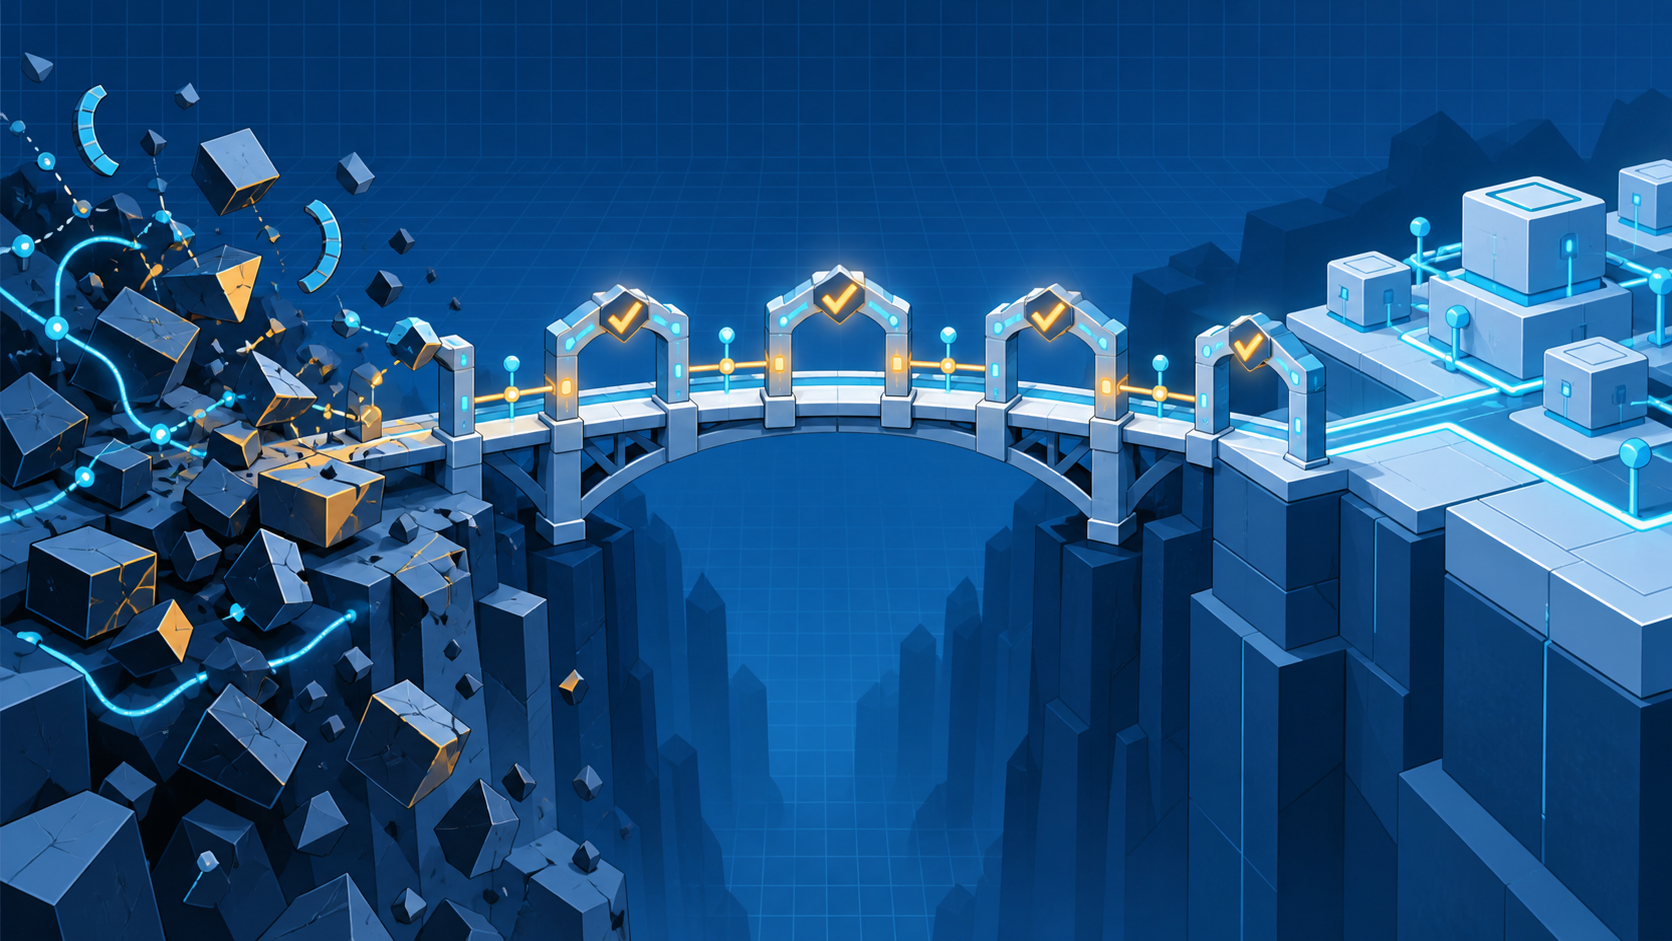
Real-SWE benchmark is a new test of coding agents on licensed private production codebases, and its first scores make a useful point: the gap between an impressive demo and dependable work inside a business is still wide.
Real-SWE benchmark: The big signal
Real-SWE, released by Specific Labs this week, evaluates agent-and-harness combinations on tasks from licensed private codebases rather than public repositories. The distinction matters. A public issue can be familiar territory for a model; a company’s billing rule, account migration or production integration is full of local conventions and business consequences.
The benchmark’s sample tasks span services and tools that look more like an operating business than a coding puzzle: databases, cloud emulators, GitHub, Linear, Slack, email and customer systems. Specific says its reference solutions change a median of 11 files. That is precisely where an agent needs more than code generation: it needs to find the right context, preserve existing behaviour and prove that the change did not break a neighbouring workflow.
The opening leaderboard is sobering rather than dismissive. Its best listed combination, Claude Fable 5.1 with Claude Code, resolves 38.8% of tasks; GPT-6 Astra with Codex CLI is listed at 33.8%, while Gemini 3.8 Flash with Gemini CLI is at 31.2%. Those are useful results, but they are not an unattended engineering team. The benchmark also reports that 6 of 10 sample tasks have resolution rates below 15%.
That makes the Real-SWE benchmark more interesting than another generic leaderboard. It measures a combination of model, tools and workflow, not a model in a vacuum. A capable model with weak repository access, vague acceptance criteria or no verification loop can still produce an expensive near-miss.
Open-source watch
There was no competing frontier-model launch in the past day that displaced this story. The open ecosystem is still moving quickly, though, and a few signals are worth tracking alongside it.
- DeepSeek V4.1 Flash remains prominent on Hugging Face. Its model card describes a one-million-token multimodal context and lower persistent KV-cache requirements, a deployment concern for long-running agents rather than a claim that they are automatically reliable.
- MiniCPM5-2B is trending as a compact open model. Small models widen the choices for private or on-device workflows, but they make careful task routing and evaluation more important, not less.
- LTX-2.5 is also trending for video generation. It is a reminder that agent systems increasingly need to handle media pipelines as well as text and code.
Open-weight progress gives smaller teams more deployment options. It does not remove the need to establish what a successful action looks like in their own environment.
What builders should take from this
For meLink, the implication is practical. An agent that helps a visitor, routes a lead or coordinates work should be designed as an operating system with boundaries, not as a single clever prompt. It needs an explicit job, a limited set of tools, a record of what it did, and a clear handoff when confidence or authority runs out.
That is the same discipline behind output contracts: define the shape, evidence and next action expected from an AI result before putting it in a customer-facing process. It also reinforces the case for fallback policies. A failed or uncertain run should not quietly become a customer promise; it should route to a safe alternate path or a person.
The Real-SWE benchmark is especially relevant to teams buying coding agents. Ask vendors to demonstrate the whole loop on a representative, non-public task: understand the request, inspect the relevant systems, make the smallest viable change, run checks, explain the result, and leave a reviewable trail. A polished answer in a blank repository is not enough.
The practical takeaway
The Real-SWE benchmark does not say coding agents are useless. It says the measurement needs to catch up with the work people want to delegate. The early results show real capability and a large reliability gap at the same time.
Small businesses and builders can act on that now: start agents on bounded, reversible work; write acceptance checks before the run; keep permissions narrow; and make human review part of the workflow for changes that touch money, customers or production systems. As agents improve, those controls become reusable infrastructure rather than friction. The teams that build them early will be better placed to use the next capability jump safely.
Leave a Reply