
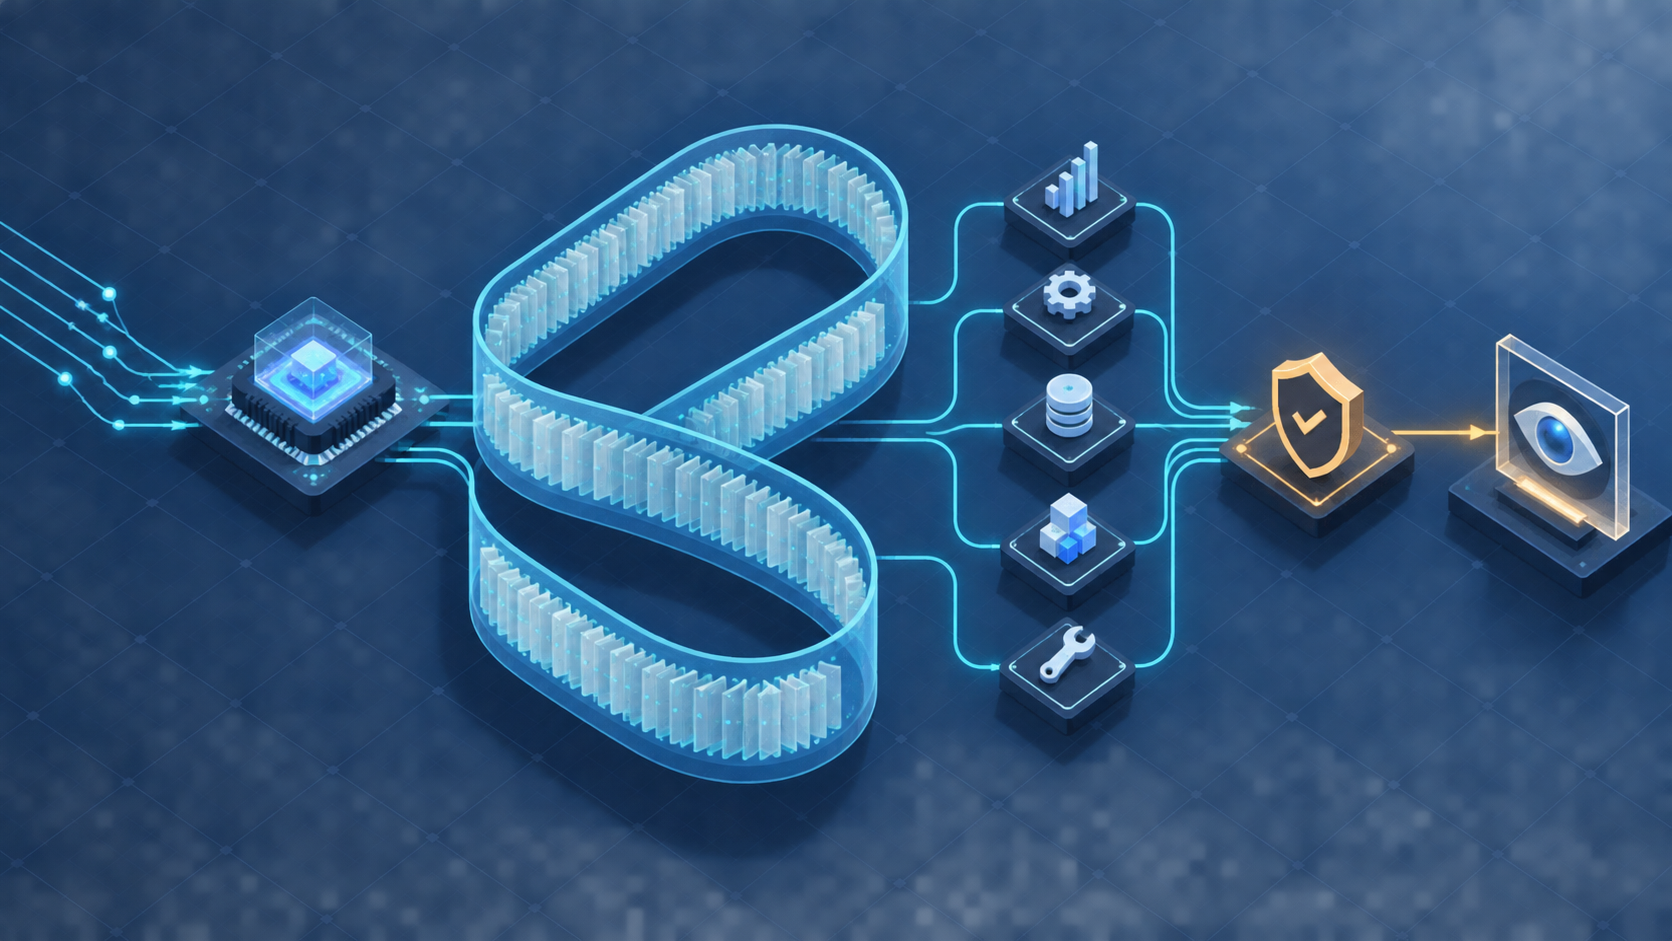
Step 5 Preview is StepFun’s new flagship model for agentic work, pairing a 1M-token context window and vision input with a sparse Mixture-of-Experts design: 600B parameters in total, but 27B active for each token. The important signal is not simply another large number. It is a direct attempt to move the price, context and capability trade-off for agents that must keep track of real work.
Step 5 Preview: the big signal
StepFun describes Step 5 Preview as a sparse Mixture-of-Experts model aimed at software engineering, professional knowledge work and finance. Its launch announcement puts the model at 600B total parameters, 27B active parameters per token, a 1M-token context window and vision input. Those are vendor claims, not an independent scorecard, but the design choice is worth watching.
For agent builders, long context is useful only when it reduces handoffs rather than creating a larger place to lose track of instructions. A model can hold a repository, a customer history or a long operating procedure, but a production agent still needs a clear task boundary, source-of-truth retrieval and a way to ask for review. That is why the more useful question is not “can it fit a million tokens?” It is “can a team make a bounded, observable workflow cheaper to run?”
The 27B-active figure matters for the same reason. Sparse models promise to activate only part of their total capacity for a token, seeking a better capability-cost balance than a dense model of comparable total scale. StepFun says Step 5 Preview sits on a better intelligence-cost frontier and reports strength on coding, agentic tasks and financial work. Treat those comparisons as a starting point for evaluation, not a procurement decision.
Where the claims need testing
A 1M-token context window changes the testing plan more than it changes the basic discipline. Teams should run a small, representative set of long tasks: a real support thread, a constrained code change, a policy-heavy research brief. Measure completion, correction rate, latency and cost together. Then test whether the agent can point to the source material it used. A large window without evidence or review is just a larger surface for confident mistakes.
That fits the case for choosing an AI model by the job, not a benchmark. It also makes the new interoperability work in Claude Code’s AGENTS.md support relevant: durable instructions and clear local rules can matter as much as a bigger context budget. Step 5 Preview should earn its place by improving a defined workflow, not by becoming the default brain for everything.
Open-source watch
The open-source counterpoint this week is PrismML’s Bonsai 2 27B GGUF. Its model card reports a 5.95 GB ternary package for a 27B-class reasoning model, 262K context and support for local CUDA, Metal and CPU paths. That is an appealing direction for teams that want more control over where prompts and documents live.
There is an important caveat: the release requires PrismML’s custom llama.cpp fork for its ternary kernels; stock llama.cpp is not presented as compatible. That is a useful reminder that “local” is not synonymous with “drop-in.” Runtime support, observability and maintenance are part of the deployment cost.
What builders should take from this
For meLink, the signal is model routing rather than model worship. A website assistant may need a quick, reliable answer with tightly scoped business knowledge. An orchestration flow may need a deeper model for a multi-step synthesis, then a human checkpoint before an action. A privacy-sensitive task may need a local or regional path. Step 5 Preview adds another option for the long-context, agentic lane; it does not remove the need to choose the lane deliberately.
- Keep long-context work separate from everyday chat and lookup tasks.
- Set a cost ceiling and a review condition before switching a workflow to a new model.
- Log the sources, tools and decisions that shaped an agent’s answer.
- Retain a fallback path when a provider, model version or tool contract changes.
The practical takeaway
Step 5 Preview makes a credible case that agent systems are becoming a contest of useful context per unit of cost, not just raw parameter counts. The winners will not be the teams that paste the longest possible history into a model. They will be the teams that use the extra room to preserve the right evidence, enforce the right boundaries and make a clear decision about when a person must step in.
That makes a sensible first experiment deliberately narrow: take one long-running task that already has a known quality bar, preserve the source pack that feeds it, and compare the new route against the current one. Keep the output reviewable and record the actual spend. If the model reduces rework or enables a job that previously had to be split apart, the larger context is doing useful work. If it merely produces a longer answer, it has not earned a permanent place in the stack.
Leave a Reply