
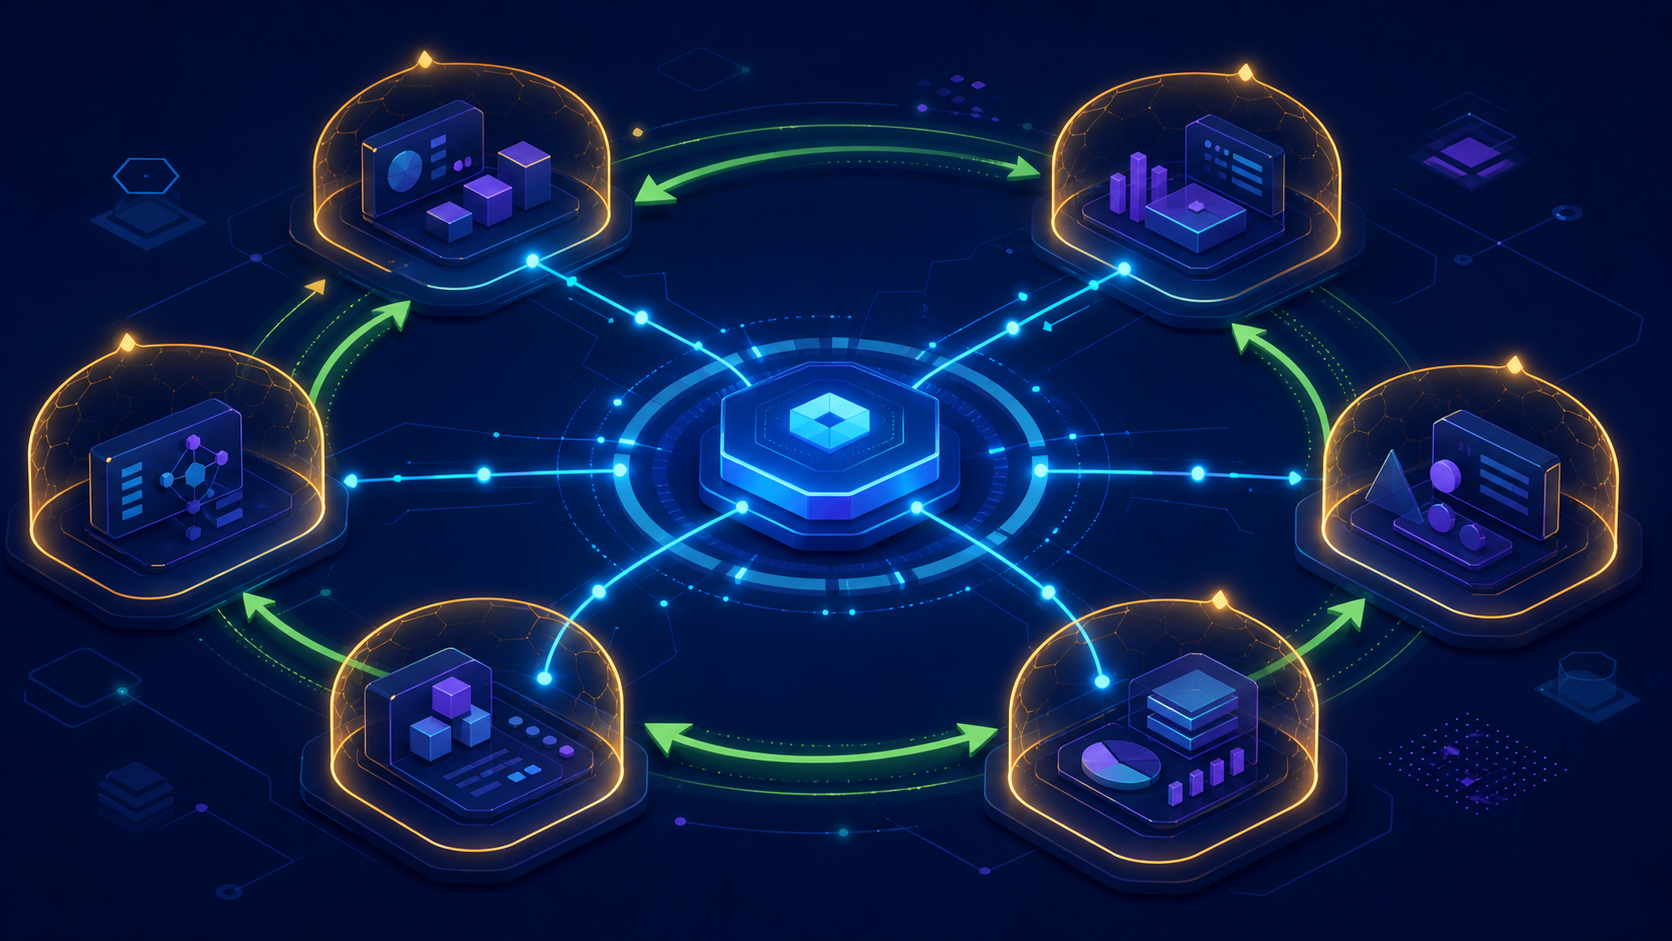
Every AI workflow will fail. The question is not whether but how badly. Most teams build their first AI workflows the way they build demos: happy path only, no guardrails, no recovery plan. When the model hallucinates a refund policy that does not exist, or sends a confident answer to the wrong customer, the damage spreads until a human notices. Fail-safe AI workflows flip that default. They treat failure as a design input, not a surprise. They bound the damage, make the failure visible, and give the team a way back without starting over.
Table of Contents
Why Most AI Workflows Break Messily
The first AI workflow a team ships is usually optimistic by design. You picked a bounded task, connected a model, got a good draft, and shipped it. The workflow works well enough that you stop watching it closely. Then the model changes, or the input drifts, or a corner case the demo never hit shows up in production, and the workflow produces something confidently wrong. Nobody notices for hours. By the time someone does, the wrong output has already reached a customer, a report, or a public-facing page.
This is the messily-breaking pattern, and it is the default. Not because teams are careless, but because the demo mindset treats failure as an exception. In a dress rehearsal, you test the happy path and a few edge cases. In production, the inputs are unbounded. The gap between “tested” and “live” is where messily-breaking workflows get exposed. Fail-safe AI workflows close that gap by assuming failure is inevitable and designing the workflow around that fact.
The NIST AI Risk Management Framework puts it plainly: AI systems should be designed to fail in predictable, bounded ways. That is not a theoretical standard. It is a practical design discipline that separates workflows you can trust from workflows you have to babysit.
Bound the Blast Radius
The first principle of fail-safe AI workflows is blast radius containment. When the AI fails, how far does the damage travel? A workflow that can send an unreviewed email to 500 customers has a blast radius of 500. A workflow that drafts the same email and holds it for a single human approval has a blast radius of one. Same model, same prompt, same output quality, completely different failure cost.
Bounding the blast radius means constraining what the workflow can do when it is wrong, before it is wrong. Three practical moves:
- Least authority. Give the workflow the minimum permissions it needs for the task. If it drafts emails, it should not have send permissions. If it writes to a database, it should write to a staging table, not the production one. The OWASP least privilege principle applies here directly: the fewer doors the workflow can open, the less damage it can do when it hallucinates.
- Batch before send. Any output that reaches a customer, a public surface, or a financial system should pass through a holding step. The AI produces a batch, a human reviews a sample or the whole batch, and only then does it go out. This is not a permanent gate. It is training wheels you remove when the correction rate is low enough to trust the lane.
- Rate limits on autonomous actions. If the workflow can act without human review, cap how many actions it can take per hour. A workflow that can send 10 emails an hour is a contained experiment. A workflow that can send 1,000 is a liability. Start low and raise the cap only after observability signals confirm the workflow is stable.
Make Failure Visible Before It Spreads
Bounded blast radius limits how far failure travels. Visibility limits how long it travels unnoticed. The two work together: a small blast radius that nobody sees for a week is still a mess. Fail-safe AI workflows make failure legible in near real time, so a human can intervene before the damage compounds.
The simplest visibility mechanism is not a dashboard. It is a notification that fires when the workflow produces something outside its normal pattern. If your website coverage agent normally hands off 5 conversations a day to the human team and suddenly hands off 20, that spike is a signal. If your report-generation workflow normally takes 30 seconds and suddenly takes 3 minutes, that latency is a signal. The Google SRE handbook makes the case that monitoring is only useful if it leads to action. The same is true for AI workflows: an alert nobody reads is worse than no alert, because it creates the illusion of supervision.
Three practical visibility moves for small teams:
- Log every autonomous action. Not for auditing later, for reviewing now. A simple shared log with timestamp, action, input summary, and output summary. Five minutes a day skimming it catches drift before it becomes damage.
- Flag low-confidence outputs. If the model returns a confidence score below your threshold, route that output to human review automatically. The threshold is a dial, not a constant. Start conservative and adjust based on what you learn.
- Detect output pattern shifts. If the workflow suddenly starts producing longer outputs, shorter outputs, or outputs with different structure, something has changed. A simple daily comparison against the previous week’s average catches this early.
Good AI gives people a way to interrupt it. Fail-safe AI workflows go further: they surface the need to interrupt before a human has to notice the problem themselves.
Build a Way Back Without Starting Over
The third principle is recoverability. When a fail-safe AI workflow breaks, the team should be able to roll back to the last known good state without rebuilding the workflow from scratch. This is where most teams discover, too late, that they have no way back. The AI wrote to the production database directly. The email went out before anyone reviewed it. The report was published to the public dashboard with no version history.
Recoverability is about designing the workflow so that undo is always possible. Three moves that make this practical:
- Write to staging first. Any AI output that modifies data, sends a message, or publishes content should land in a staging surface first. Staging is reviewable, reversible, and cheap. Production is none of those things. The distance between staging and production is your safety margin.
- Version every prompt and config. When the workflow degrades after a prompt change, you need to know what changed and roll it back in one step. A folder of dated prompt files is enough. The point is not sophistication. The point is that “revert to last Tuesday’s prompt” takes 30 seconds, not 30 minutes of git archaeology.
- Keep the human fallback warm. The old way of doing the task, the manual process the AI replaced, should not be forgotten. Run it once a month on one input to confirm it still works. When the AI workflow fails badly, you need to be able to fall back to the manual process for a day while you fix it. A fallback you have never tested is not a fallback. It is a hope.
The Three-Question Pre-Flight Check
Before shipping any AI workflow, run it through three questions. If any answer is unsatisfying, do not ship. These are the fail-safe AI workflows pre-flight check:
- What is the blast radius if this workflow is confidently wrong? Name the worst realistic failure and count how many people, records, or dollars it touches. If the number feels too high, add a gate.
- How quickly will a human know something went wrong? If the answer is “when a customer complains,” that is too slow. Add a notification or a pattern-shift detector.
- Can we undo the last hour of work in under five minutes? If not, add a staging step, version the config, or keep the manual fallback warm. Recoverability is a design choice, not a hope.
These questions are not a gate you pass once. They are a check you run every time the workflow changes scope, model, or input domain. Knowing when not to use AI is the first filter. Knowing how to contain the damage when you do use it is the second.
Fail-Safe AI Workflows Are Not Fail-Proof
A fail-safe AI workflow is not one that never fails. It is one that fails small, fails visibly, and fails recoverably. The goal is not perfection. The goal is a workflow you can trust enough to let run unsupervised for an hour, then a morning, then a day, because you know that when it breaks, the damage is bounded, the signal is loud, and the way back is short.
Teams that internalise this discipline ship AI workflows faster over time, not slower. They remove approval gates sooner because they trust the blast radius is contained. They automate monitoring sooner because they built the signals in from the start. They recover from failures in minutes because they designed the workflow to be undone. The teams that skip this discipline either babysit their AI forever or learn the cost of messily-breaking workflows the hard way.
Build for the failure you know is coming. Bound it, surface it, and keep a way back. That is the whole practice. The model will do its job. Your job is to make sure that when it does not, the damage is small enough to fix before anyone else notices.

Leave a Reply